- Sep 20, 2023
-
-
Hans Wennborg authored
Revert "[clang] Don't inherit dllimport/dllexport to exclude_from_explicit_instantiation members during explicit instantiation (#65961)"

This uncovered a problem with virtual methods and
exclude_from_explicit_instantiation, see
https://github.com/llvm/llvm-project/issues/66909

Reverting until that's fixed.

> This is a continuation of https://reviews.llvm.org/D155713
>
> Fixes https://github.com/llvm/llvm-project/issues/40363

This reverts commit 84216d17.
-
Walter Erquinigo authored
Auto summaries were only being used when non-pointer/reference variables
didn't have values nor summaries. Greg pointed out that it should be
better to simply use auto summaries when the variable doesn't have a
summary of its own, regardless of other conditions.

This led to code simplification and correct visualization of auto
summaries for pointer/reference types, as seen in this screenshot.

<img width="310" alt="Screenshot 2023-09-19 at 7 04 55 PM"
src="https://github.com/llvm/llvm-project/assets/1613874/d356d579-13f2-487b-ae3a-f3443dce778f">
-
Alex Bradbury authored
This fixes the -DBUILD_SHARED_LIBS=True build, which broke after #66730.
-
Luís Marques authored
This patch warns when an align directive with a non-zero fill value is
used in a virtual section. The fill value is also set to zero,
preventing an assertion in `MCAssembler::writeSectionData` for the case
of `MCFragment::FT_Align` from tripping.
-
Benjamin Maxwell authored
This extends `vector.constant_mask` so that mask dim sizes that
correspond to a scalable dimension are treated as if they're implicitly
multiplied by vscale. Currently this is limited to mask dim sizes of 0
or the size of the dim/vscale. This allows constant masks to represent
all true and all false scalable masks (and some variations):

```
// All true scalable mask
%mask = vector.constant_mask [8] : vector<[8]xi1>

// All false scalable mask
%mask = vector.constant_mask [0] : vector<[8]xi1>

// First two scalable rows
%mask = vector.constant_mask [2,4] : vector<4x[4]xi1>
```
-
Louis Dionne authored
This makes it easier to compare the features available in two adjacent
runs of lit.
-
Simon Pilgrim authored
[X86] X86DAGToDAGISel::matchIndexRecursively - replace hard coded recursion limit with SelectionDAG::MaxRecursionDepth. NFCI.
-
Matt Devereau authored
This change makes callees with the __arm_preserves_za
type attribute comply with the dormant state requirements
when it's caller has the __arm_shared_za type attribute.
Several external SME functions also do not need to lazy
save.

https://github.com/ARM-software/abi-aa/blob/5e67092434b50c04f8ad178a9c272ce3c6ada7fd/aapcs64/aapcs64.rst?plain=1#L1381

Differential Revision: https://reviews.llvm.org/D159186
-
Louis Dionne authored
Instead of relying on Bash, use the builtin Lit commands whenever
possible. The motivation is to stop running %t.exe behind Bash, which
breaks on macOS 13.5 with SIP enabled because DYLD_LIBRARY_PATH isn't
forwarded to the underlying process when running through a protected
process.

For more details, see [1].

[1]: https://developer.apple.com/library/archive/documentation/Security/Conceptual/System_Integrity_Protection_Guide/RuntimeProtections/RuntimeProtections.html
-
Natalie Chouinard authored
Previously, the SPIR-V instruction printer was always printing the first
operand of an `OpConstant`'s literal value as one of the fixed operands.
This is incorrect for 64-bit values, where the first operand is actually
the value's lower-order word and should be combined with the following
higher-order word before printing.

This change fixes that issue by waiting to print the last fixed operand
of `OpConstant` instructions until the variadic operands are ready to be
printed, then using `NumFixedOps - 1` as the starting operand index for
the literal value operands.

Depends on D156049
-
Abhinav271828 authored
[MLIR][Presburger] Template Matrix to allow MPInt and Fraction; use IntMatrix for integer matrices (#66897)

Matrix has been templated to Matrix (for MPInt and Fraction) with
explicit instantiation for both these types.
IntMatrix, inheriting from Matrix<MPInt>, has been created to allow for
integer-only methods.
makeMatrix has been duplicated to makeIntMatrix and makeFracMatrix.

This was already landed previously but was reverted in
98c994c8 due to build failure. This
fixes the failure.
-
martinboehme authored
Previously, post-visit state changes were indistinguishable from ordinary iterations, which could give a confusing picture of how many iterations a block needs to converge. Now, post-visit state changes are marked with "post-visit" instead of an iteration number: 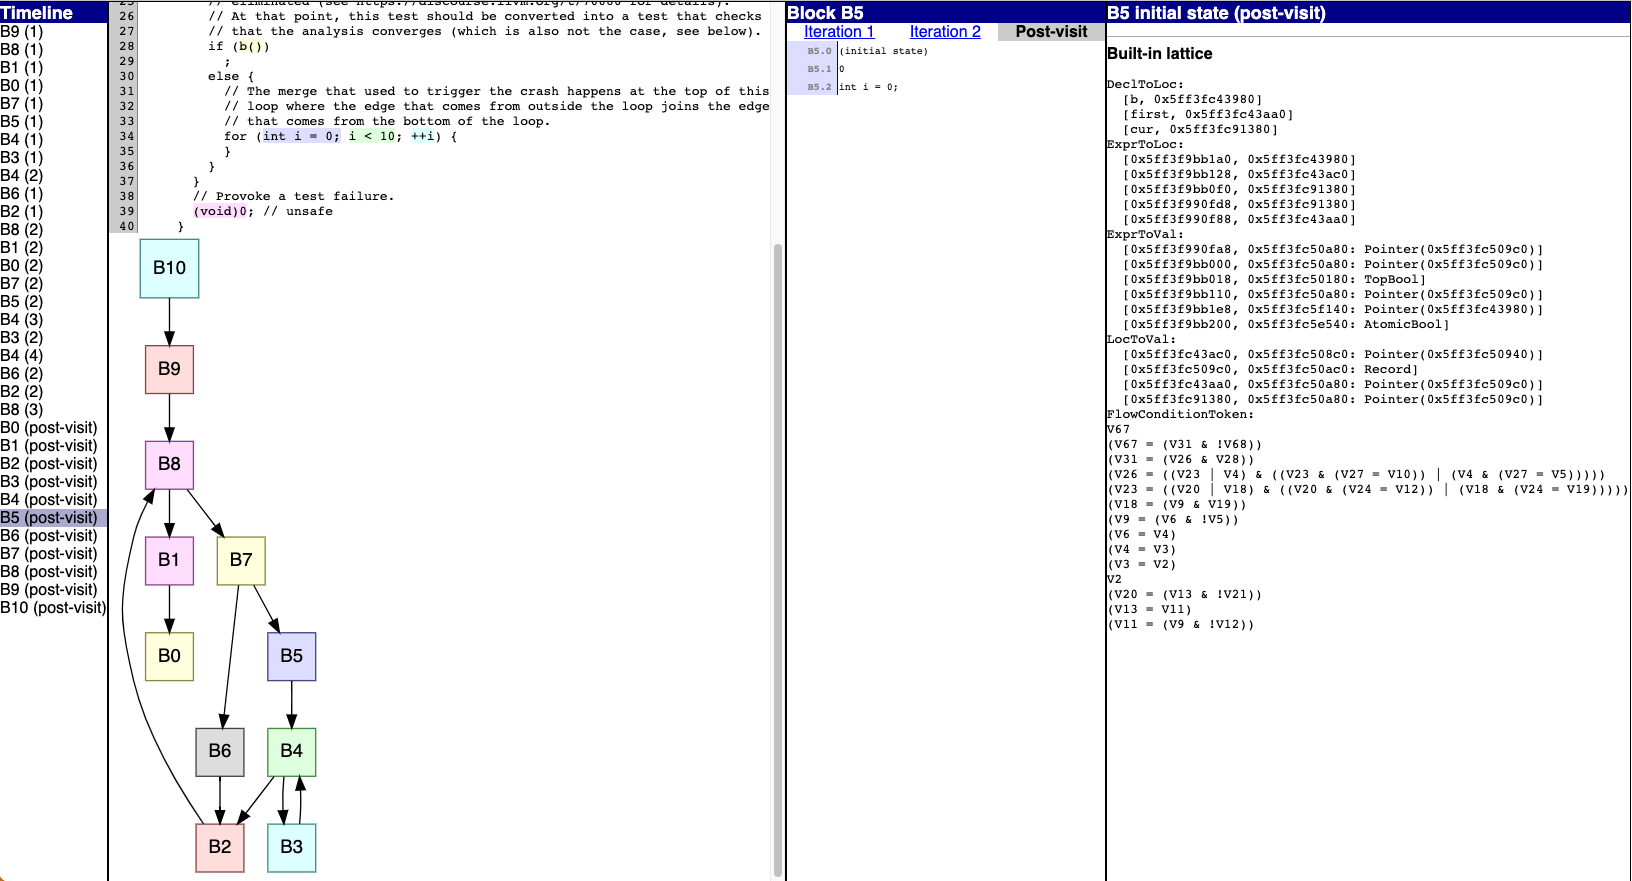)
-
Freddy Ye authored
-
Freddy Ye authored
For *_stream_* series intrinsics
-
Martin Erhart authored
[mlir][bufferization][NFC] Move memref specific implementation of AllocationOpInterface to memref dialect directory (#66637)

Follow-up on #65578
-
Nikita Popov authored
Fix some syntax errors and use opaque pointers.
-
Timm Bäder authored
-
Luke Lau authored
This adds tests for fixed and scalable vectors where we have a binary op
on two splats that could be scalarized. Normally this would be
scalarized in the middle-end by VectorCombine, but as noted in
https://reviews.llvm.org/D159190, this pattern can crop up during
CodeGen afterwards.

Note that a combine already exists for this, but on RISC-V currently it
only works on scalable vectors where the element type == XLEN. See
#65068 and #65072
-
Martin Erhart authored
This is necessary to run the new buffer deallocation pipeline as part of
the sparse compiler pipeline.
-
Nikita Popov authored
For volatile atomic, this may result in a verifier errors, if the
new alloca type is not legal for atomic accesses.

I've opted to disable this special case for volatile accesses in
general, as changing the size of the volatile access seems
dubious in any case.

Fixes https://github.com/llvm/llvm-project/issues/64721.
-
Juan Manuel MARTINEZ CAAMAÑO authored
-
Juan Manuel MARTINEZ CAAMAÑO authored
-
Kazushi Marukawa authored
Add unittest for VE intrinsics instructions.
-
Balazs Benics authored
Basically, the issue was that we should have unwrapped the
base region before we special handle temp object regions.

Fixes https://github.com/llvm/llvm-project/issues/66221

I also decided to add some extra range information to the diagnostics
to make it consistent with the other reporting path.
-
Juan Manuel Martinez Caamaño authored
Addressing remarks after merge of D159257

* Add comment
* Remove irrelevant CHECKs from test
* Simplify function
* Use llvm::sort before setting target-features as it is done in
CodeGenModeule
-
Simon Pilgrim authored
Test file showing current codegen for D124406
-
Simon Pilgrim authored
If all the concatenated subvectors are targets shuffle nodes, then call combineX86ShufflesRecursively to attempt to combine them.

Unlike the existing shuffle concatenation in collectConcatOps, this isn't limited to splat cases and won't attempt to concat the source nodes prior to creating the larger shuffle node, so will usually only combine to create cross-lane shuffles.

This exposed a hidden issue in matchBinaryShuffle that wasn't limiting v64i8/v32i16 UNPACK nodes to AVX512BW targets.
-
Simon Pilgrim authored
These aren't always used but its lot more manageable to keep the vector-interleaved files using the same RUN lines wherever possible
-
Liqiang Tao authored
This patch fixes a memory leak if Function::dropAllReferences() is followed by setHungoffOperand (e.g. setPersonality)
If NumUserOperands changes from 3 to 0 before calling allocHungoffUselist() to allocate memory,
the memory leaks which are allocated when NumUserOperands is changed from 0 to 3.
e.g.
```
llvm::Function* func = ...;
func->setPersonalityFn(foo);  // (1). call allocHungoffUselist() to allocate memory for uses
func->deleteBody();  // (2). call dropAllReferences(), and it changes NumUserOperands from 3 to 0
// (3). at this point, NumUserOperands is 0, the next line will allocate memory by allocHungoffUselist()
func->setPersonalityFn(bar);  // (4). call allocHungoffUselist(), so memory allocated in (1) leaks.
```

Reviewed By: dexonsmith, MaskRay

Differential Revision: https://reviews.llvm.org/D156618
-
vabridgers authored
evalIntegralCast was using makeIntVal, and when _BitInt() types were
introduced this exposed a crash in evalIntegralCast as a result.

This is a reapply of a previous patch that failed post merge on the arm
buildbots, because arm cannot handle large
BitInts. Pinning the triple for the testcase solves that problem.

Improve evalIntegralCast to use makeIntVal more efficiently to avoid the
crash exposed by use of _BitInt.

This was caught with our internal randomized testing.

<src-root>/llvm/include/llvm/ADT/APInt.h:1510:
  int64_t llvm::APInt::getSExtValue() const: Assertion
  `getSignificantBits() <= 64 && "Too many bits for int64_t"' failed.a

...
 #9 <address> llvm::APInt::getSExtValue() const
  <src-root>/llvm/include/llvm/ADT/APInt.h:1510:5
  llvm::IntrusiveRefCntPtr<clang::ento::ProgramState const>,
  clang::ento::SVal, clang::QualType, clang::QualType)
  <src-root>/clang/lib/StaticAnalyzer/Core/SValBuilder.cpp:607:24
clang::Expr const*, clang::ento::ExplodedNode*,
clang::ento::ExplodedNodeSet&)
  <src-root>/clang/lib/StaticAnalyzer/Core/ExprEngineC.cpp:413:61
...

 Fixes: https://github.com/llvm/llvm-project/issues/61960

 Reviewed By: donat.nagy
-
Martin Erhart authored
This is necessary to support deallocation of IR with gpu.launch
operations because it does not implement the RegionBranchOpInterface.
Implementing the interface would require it to support regions with
unstructured control flow and produced arguments/results.
-
Brandon Wu authored
If we don't include riscv_vector.h, even we add the target-feature,
it still can't find the intrinsic interface.
-
Kiran Chandramohan authored
As part of preparing for the switch to HLFIR lowering, all OpenMP FIR
lowering tests are moved to a subdirectory in the OpenMP directory.
Copies of these tests that work with HLFIR will be created during this
week. After the switch the FIR lowering tests will be removed.

All new tests should be added with the HLFIR flow.
-
vabridgers authored
This crash was exposed recently in our randomized testing. _BitInts were not being handled properly during IntegerLiteral visitation. This patch addresses the problem for now. The BitIntType has no getKind() method, so the FoldingSetID is taken from the APInt value representing the _BitInt(), similar to other methods in StmtProfile.cpp. Crash seen (summary form): clang-tidy: <src-root>/llvm/include/llvm/Support/Casting.h:566: decltype(auto) llvm::cast(const From&) [with To = clang::BuiltinType; From = clang::QualType]: Assertion `isa<To>(Val) && "cast<Ty>() argument of incompatible type!"' failed ``` #9 <address> decltype(auto) llvm::cast<clang::BuiltinType, clang::QualType>(clang::QualType const&) <src-root>/llvm/include/llvm/Support/Casting.h:566:3 #10 <address> clang::BuiltinType const* clang::Type::castAs<clang::BuiltinType>() const <bin-root>/tools/clang/include/clang/AST/TypeNodes.inc:86:1 #11 <address> (anonymous namespace)::StmtProfiler::VisitIntegerLiteral( clang::IntegerLiteral const*) <src-root>/clang/lib/AST/StmtProfile.cpp:1362:64 #12 <address> clang::StmtVisitorBase<llvm::make_const_ptr, (anonymous namespace)::StmtProfiler, void>::Visit(clang::Stmt const*) <src-root>/clang/include/clang/AST/StmtNodes.inc:1225:1 ``` Reviewed By: donat.nagy -
David Spickett authored
-
Sameer Sahasrabuddhe authored
The entry and loop intrinsics for convergence control cannot be preceded
by convergent operations in their respective basic blocks. To check
that, the verifier needs to reset its state at the start of the block.
This was missed in the previous commit
fa6dd7a24af2b02f236ec3b980d9407e86c2c4aa.
-
Aleksandr Popov authored
In the d6e7c162 was introduced util to
to extract widenable conditions from branch. That util was applied in
the llvm::isWidenableBranch to check if branch is widenable. So we
consider branch is widenable if it has widenable condition anywhere in
the condition tree. But that will be true when we finish GuardWidening
reworking from branch widening to widenable conditions widening.
For now we still need to check that widenable branch is in the form of:
`br(widenable_condition & (...))`,
because that form is assumed by LoopPredication and GuardWidening
algorithms.

Fixes: https://github.com/llvm/llvm-project/issues/66418


Co-authored-by: Aleksander Popov <apopov@azul.com>
-
Guillaume Chatelet authored
This is a reland of #66783 a35a3b75
fixing the benchmark breakage.
-
David Spickett authored
Software can tell if it is in streaming SVE mode by checking
the Streaming Vector Control Register (SVCR).

"E3.1.9 SVCR, Streaming Vector Control Register" in
"Arm® Architecture Reference Manual Supplement, The Scalable Matrix
Extension (SME), for Armv9-A"

https://developer.arm.com/documentation/ddi0616/latest/

This is especially useful for debug because the names of the
SVE registers are the same betweeen non-streaming and streaming mode.

The Linux Kernel chose to not put this register behind ptrace,
and it can be read from EL0. However, this would mean running code
in process to read it. That can be done but we already know all
the information just from ptrace.

So this is a pseudo register that matches the architectural
content. The name is just "svcr", which aligns with GDB's proposed naming,
and it's added to the existing SME register set.

The SVCR register contains two bits:
0 : Whether streaming SVE mode is enabled (SM)
1 : Whether the array storage is enabled (ZA)

Array storage can be active when streaming mode is not, so this register
can have any permutation of those bits.

This register is currently read only. We can emulate the result of
writing to it, using ptrace. However at this point the utility of that
is not obvious.

Existing tests have been updated to check for appropriate SVCR values
at various points.

Given that this register is a read only pseudo, there is no need
to save and restore it around expressions.

Reviewed By: omjavaid

Differential Revision: https://reviews.llvm.org/D154927
-
Andrzej Warzyński authored
Extend `ReorderElementwiseOpsOnBroadcast` so that the broadcasting op
could be either `vector.broadcast` (already supported) as well as
`vector.splat` (support added in this patch).
-


