- Feb 15, 2024
-
-
Christian Sigg authored
-
Christian Sigg authored
-
ostannard authored
This adds support for the AArch64 soft-float ABI. The specification for
this ABI was added by https://github.com/ARM-software/abi-aa/pull/232.

Because all existing AArch64 hardware has floating-point hardware, we
expect this to be a niche option, only used for embedded systems on
R-profile systems. We are going to document that SysV-like systems
should only ever use the base (hard-float) PCS variant:
https://github.com/ARM-software/abi-aa/pull/233. For that reason, I've
not added an option to select the ABI independently of the FPU hardware,
instead the new ABI is enabled iff the target architecture does not have
an FPU.

For testing, I have run this through an ABI fuzzer, but since this is
the first implementation it can only test for internal consistency
(callers and callees agree on the PCS), not for conformance to the ABI
spec.
-
Christian Sigg authored
-
David Spickett authored
Flang does not set the preprocessor define.
-
Jay Foad authored
-
Leandro Lupori authored
This adds a new custom CopyPrivateVarList to the single operation.
Each list item is formed by a reference to the variable to be
updated, its type and the function to be used to perform the copy.

It will be translated to LLVM IR using OpenMP builder, that will
use the information in the copyprivate list to call
__kmpc_copyprivate.

This is patch 2 of 4, to add support for COPYPRIVATE in Flang.
Original PR: https://github.com/llvm/llvm-project/pull/73128
-
NAKAMURA Takumi authored
Fixup for #81227
-
NAKAMURA Takumi authored
-
Jacek Caban authored
Add new target and a new -n option allowing to specify native module
definition file, similar to how -defArm64Native works in llvm-lib. This
also changes archive format to use K_COFF like non-mingw targets. It's
required on ARM64EC, but it should be fine for other targets too.
-
Simon Pilgrim authored
[X86] shuffle combines - share the same SDLoc argument instead of recreating it over and over again.
-
Simon Pilgrim authored
-
Simon Pilgrim authored
If the source is being (logically) shifted, but doesn't affect any active bits, then we can call CTPOP on the shift source directly.
-
Jay Foad authored
When a whole register is added a basic block's liveins, use
LaneBitmask::getAll for the live lanes instead of trying to calculate an
accurate mask of the lanes that comprise the register.

This simplifies the code and matches other places where a whole register
is marked as livein.

This also avoids problems when regunits that are synthesized by TableGen
to represent ad hoc aliasing have a lane mask of 0.

Fixes #78942
-
Cullen Rhodes authored
Currently marked as XFAIL due to bug in QEMU. See test for details.
-
Vyacheslav Levytskyy authored
This PR adds support for the SPV_KHR_linkonce_odr extension and modifies
existing negative test with a positive check for the extension and
proper linkage type in case when the extension is enabled.

SPV_KHR_linkonce_odr adds a "LinkOnceODR" linkage type, allowing proper
translation of, for example, C++ templates classes merging during
linking from different modules and supporting any other cases when a
global variable/function must be merged with equivalent global
variable(s)/function(s) from other modules during the linking process.
-
Vyacheslav Levytskyy authored
By SPIR-V specification: "If an instruction, enumerant, or other feature
specifies multiple enabling capabilities, only one such
capability needs to be declared to use the feature."

However, one capability may be preferred over another. One important
case is Shader capability that may not be supported by a backend, but
always is inserted if "OpDecorate SpecId" is found, because Enabling
Capabilities for the latter is the list of Shader and Kernel, where
Shader is coming first and thus always selected as the first available
option.

In this PR we address the problem by keeping current behaviour of
selecting the first option among enabling capabilities as is, but giving
a user a way to filter capabilities during the selection process via a
newly introduced "--avoid-spirv-capabilities" command line option. This
option is to avoid selection of certain capabilities if there are other
available enabling capabilities.

This PR is changing also existing pruneCapabilities() function. It
doesn't remove capability from module requirement anymore, but only adds
implicitly required capabilities recursively, so its name is changed
accordingly. This change fixes the present bug in collecting required by
a module capabilities. Before the change, introduced by this PR,
pruneCapabilities() function has been removing, for example, Kernel
capability from required by a module, because Kernel is initially
required and the second time it was needed pruneCapabilities() removed
it by mistake.
-
David Spickett authored
Currently https://flang.llvm.org/docs/FlangCommandLineReference.html
refers to "Clang" in several of the group descriptions for example:
```
Compilation options

Flags controlling the behavior of Clang during compilation...
```

This is pretty confusing. I'm fixing this by making use of `Program`
from the existing GlobalDocumentation object to substitute in the
program name to these descriptions.

This `Program` has been changed to a proper noun given that it's easier
to lower case a string than capitalise one character (syntax wise). The
tablegen backend has been changed to lower it so that links in the
RST/HTML remain the same as they were before.

To make sure the file is valid when not generating docs, I'm checking a
#define and providing a default GlobalDocumentation if it's not defined.
(I looked for a way to check if a def exists, but tablegen doesn't seem
to have one)

This means that if the Do...
-
chuongg3 authored
The combine now works using tablegen and checks if new instruction is
legal before creating it.
-
Stanislav Mekhanoshin authored
I need these operands for a future patch. Also simplify conditions
there. If nothing using !cond instead of nesting !if's does not need to
realign code every time a new type is added.
-
Paul Semel authored
-
Mikael Holmen authored
Without the fix gcc warns like ../../clang/lib/Sema/SemaDecl.cpp:2963:24: warning: unused variable 'SupA' [-Wunused-variable] 2963 | else if (const auto *SupA = dyn_cast<SuppressAttr>(Attr)) | ^~~~ and ../../clang/lib/Driver/Driver.cpp:4192:17: warning: unused variable 'IAA' [-Wunused-variable] 4192 | if (auto *IAA = dyn_cast<InstallAPIJobAction>(Current)) { | ^~~ Remove the unused variables and change the "dyn_cast"s into "isa"s. -
-
jeanPerier authored
When doing a pointer assignment with an RHS that is an array section,
the code fell in the legacy lowering code even with HLFIR enabled.
Escape this old code when HLFIR is on.

Should fix #80884.
-
jeanPerier authored
Spread, reshape, pack, and other transformational intrinsic runtimes are
using `CopyElement` utility to copy elements. This utility was dealing
with deep copies, but only when the allocatable components where
"immediate" components of the type being copied. If the allocatable
components were nested inside a nonpointer/nonallocatable component,
they were not deep copied, leading to bugs later when manipulating the
value (or double free when applying #81117).

Visit data components with allocatable components (using the
noDestructionNeeded flag to avoid expensive and useless type visit when
there are no such components).
-
jeanPerier authored
The runtime was currently only deallocating the direct allocatable
components, which caused leaks when there are allocatable components
nested in the direct components.

Update Destroy to recursively destroy components.

Also call Destroy from Assign to deallocate nested allocatable
components before doing the assignment as required by F2018 9.7.3.2
point 7.

This lack of deallocation was visible if the nested components had user
defined assignment "observing" the allocation state.
-
Christian Sigg authored
-
NAKAMURA Takumi authored
Also, Let `NumConditions` `uint16_t`.

It is smarter to handle the ID as signed.
Narrowing to `int16_t` will reduce costs of handling byvalue. (See also
#81221 and #81227)

External behavior doesn't change. They below handle values as internal
values plus 1.
* `-dump-coverage-mapping`
* `CoverageMappingReader.cpp`
* `CoverageMappingWriter.cpp`
-
Rohit Aggarwal authored
Hi,

AMD has it's own implementation of vector calls. This patch include the
changes to enable the use of AMD's math library using -fveclib=AMDLIBM.
Please refer https://github.com/amd/aocl-libm-ose


---------

Co-authored-by: Rohit Aggarwal <Rohit.Aggarwal@amd.com>
-
Timm Bäder authored
-
Timm Bäder authored
Checking for isConstexpr() is wrong; we need to (try to) call
the function and let later code diagnose the failure accordingly.
-
-
riChar authored
VERR/VERW instructions will define ZF flag.
-
Owen Pan authored
-
Abhinav271828 authored
[MLIR][Presburger] Implement vertex enumeration and chamber decomposition for polytope generating function computation. (#78987)

We implement a function to compute the generating function corresponding
to a full-dimensional parametric polytope whose tangent cones are all
unimodular.
We fix a bug in unimodGenFunc to check the absolute value of the index.
We also implement Matrix<T>::negateMatrix() and Matrix<T>::scaleRow for
convenience.
-
Timm Bäder authored
For variadic member functions, the way we calculated the instance
pointer and RVO pointer offsts on the stack was incorrect, due
to Func->getArgSize() not returning the full size of all the
passed arguments. When calling variadic functions, we need
to pass the size of the passed (variadic) arguments to the Call*
ops, so they can use that information to properly check the
instance pointer, etc.

This patch adds a bit of code duplication in Interp.h, which I
will get rid of in later cleanup NFC patches.
-
Qfrost authored
[@xia0ji233](https://github.com/xia0ji233) and I found that X86::LAR and X86::lSR implicit use eflags register. However, it was not been defined in LLVM, which means we will get wrong alive-result if we use these two instructions. 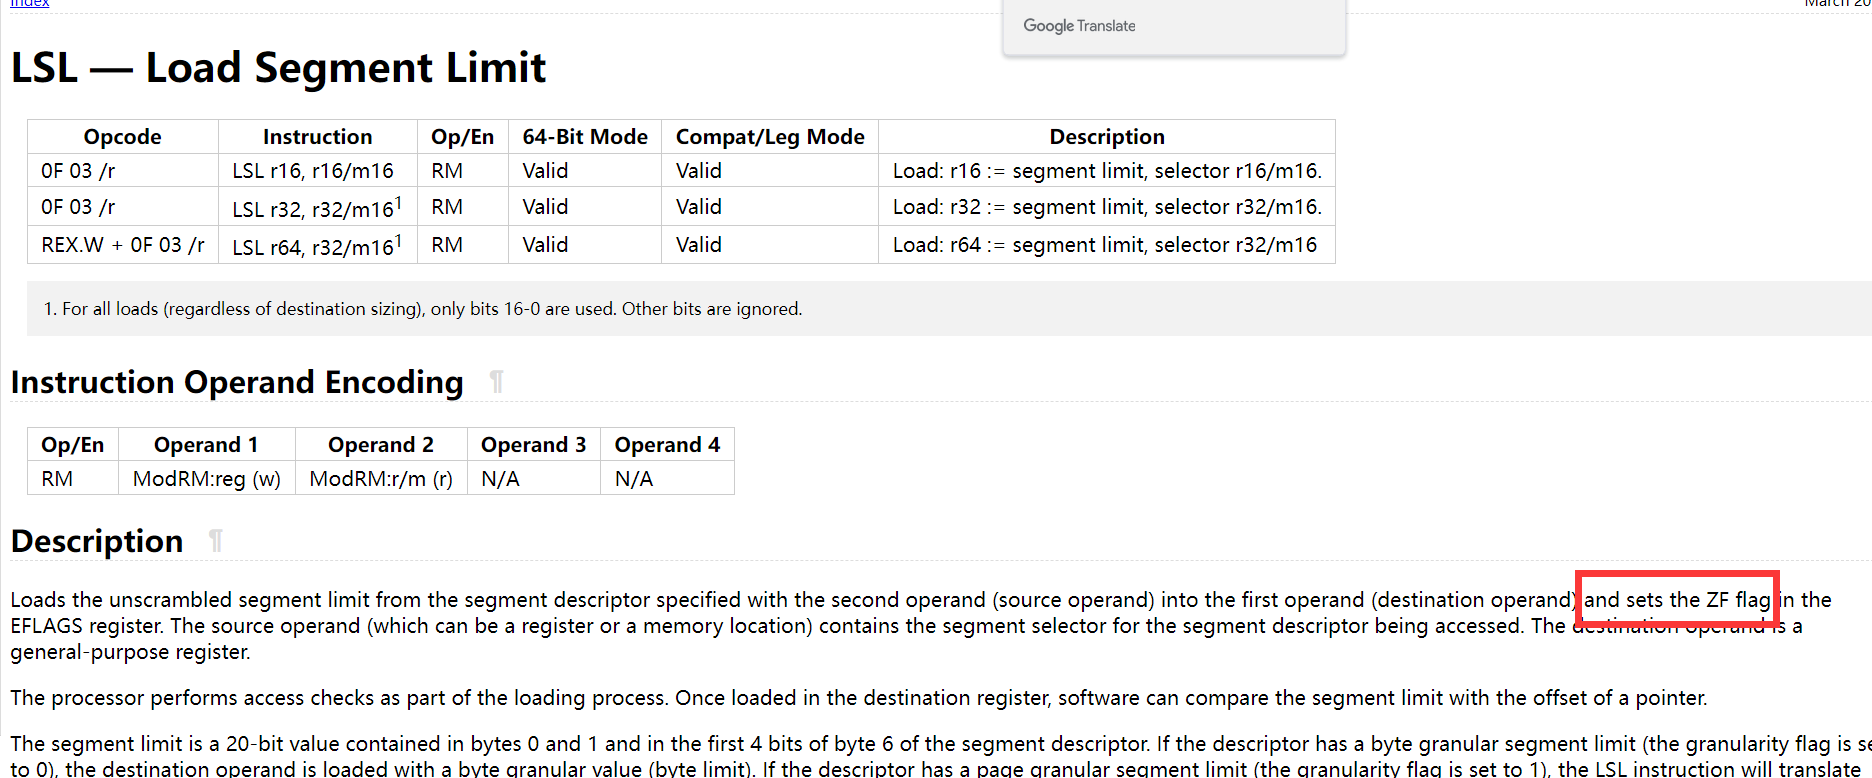
-
Joseph Huber authored
-
Luke Lau authored
For llvm.vector.extract, this tests combinations of inserting at a zero and
non-zero index, and extracting from a fixed or scalable vector.

For llvm.vector.insert, this tests the same combinations as extracts but with
an additional configuration for an undef vector. This is because we can use a
subregister insert if the index is 0 and the vector is undef, which should be
free.
-
Joseph Huber authored
Summary:
This is necessary because CMake build tools might need to generate
several files but are unable to put them in separate images. This patch
sipmly moves the file handling out into a separate split iterator.
-


