- Nov 30, 2023
-
-
Jeremy Morse authored
Because we're storing some extra debug-info information in the iterator
class, we need to insert new LICM-created stores using such iterators.
Switch LICM to storing iterators instead of pointers when it promotes
variables in loops, add a test for the desired behaviour, and enable
RemoveDIs instrumentation on a variety of other LICM tests for good
measure.

(This would appear to be the only pass in LLVM that needs to store
iterators on the heap).
-
Nikita Popov authored
For parity with computeKnownBits(). This came up when adding a
consistency assertion.
-
Guillaume Chatelet authored
Once this is submitted we can remove `include/__support/bit.h` that
duplicates some of this functionality.
-
Jeremy Morse authored
Here's a problem for the RemoveDIs project to make debug-info not be stored in instructions -- in the following sequence: dbg.value(foo %bar = add i32 ... dbg.value(baz It's possible for rare passes (only CodeGenPrepare) to remove the add instruction, and then re-insert it back in the same place. When debug-info is stored in instructions and there's a total order on "when" things happen this is easy, but by moving that information out of the instruction stream we start having to do manual maintenance. This patch adds some utilities for re-inserting an instruction into a sequence of DPValue objects. Someday we hope to design this away, but for now it's necessary to support all the things you can do with dbg.values. The two unit tests show how DPValues get shuffled around using the relevant function calls. A follow-up patch adds instrumentation to CodeGenPrepare. -
Guillaume Chatelet authored
-
Mariya Podchishchaeva authored
Initialize field so there is no use-of-uninitialized-value warning.
-
Rik Huijzer authored
Fixes https://github.com/llvm/llvm-project/issues/64269.

With this patch, calling `mlir-opt "-convert-vector-to-scf=full-unroll
target-rank=0"` on
```mlir
func.func @main(%vec : vector<2xi32>) {
  %alloc = memref.alloc() : memref<4xi32>
  %c0 = arith.constant 0 : index
  vector.transfer_write %vec, %alloc[%c0] : vector<2xi32>, memref<4xi32>
  return
}
```
will result in
```mlir
module {
  func.func @main(%arg0: vector<2xi32>) {
    %c0 = arith.constant 0 : index
    %c1 = arith.constant 1 : index
    %alloc = memref.alloc() : memref<4xi32>
    %0 = vector.extract %arg0[0] : i32 from vector<2xi32>
    %1 = vector.broadcast %0 : i32 to vector<i32>
    vector.transfer_write %1, %alloc[%c0] : vector<i32>, memref<4xi32>
    %2 = vector.extract %arg0[1] : i32 from vector<2xi32>
    %3 = vector.broadcast %2 : i32 to vector<i32>
    vector.transfer_write %3, %alloc[%c1] : vector<i32>, memref<4xi32>
    return
  }
}
```

I've also tried to proactively find other `target-rank=0` bugs, but
couldn't find any. `options.targetRank` is only used 8 times throughout
the `mlir` folder, all inside `VectorToSCF.cpp`. None of the other uses
look like they could cause a crash. I've also tried

```mlir
func.func @main(%vec : vector<2xi32>) -> vector<2xi32> {
  %alloc = memref.alloc() : memref<4xindex>
  %c0 = arith.constant 0 : index
  %out = vector.transfer_read %alloc[%c0], %c0 : memref<4xindex>, vector<2xi32>
  return %out : vector<2xi32>
}
```
with `"--convert-vector-to-scf=full-unroll target-rank=0"` and that also
didn't crash. (Maybe obvious. I have to admit that I'm not very familiar
with these ops.)
-
Jeremy Morse authored
Part of the "RemoveDIs" project to remove debug intrinsics requires
passing block-positions around in iterators rather than as instruction
pointers, allowing some debug-info to reside in BasicBlock::iterator.
This means getInsertionPointAfterDef has to return an iterator, and as
it can return no-instruction that means returning an optional iterator.

This patch changes the signature for getInsertionPtAfterDef and then
patches up the various places that use it to handle the different type.
This would overall be an NFC patch, however in
InstCombinerImpl::freezeOtherUses I've started skipping any debug
intrinsics at the returned insert-position. This should not have any
_meaningful_ effect on the compiler output: at worst it means variable
assignments that are skipped will now cover the freeze instruction and
anything inserted before it, which should be inconsequential.

Sadly: this makes the function signature ugly...
-
David Green authored
-
Paul Walker authored
NOTE: I'm not sure how many of the corner cases are part of the
documented ABI but that shouldn't matter because my goal is for
`-msve-vector-bits` to have no affect on the way arguments and returns
are processed.
-
Antonio Frighetto authored
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Jean Perier authored
Added by mistake in https://github.com/llvm/llvm-project/pull/73658.
Not needed and breaks shared library builds.
-
Momchil Velikov authored
-
Michael Buch authored
The check for this was removed in
https://github.com/llvm/llvm-project/pull/72974

This patch removes the member from the source itself since
it was confusing FileCheck
-
Antonio Frighetto authored
Support `icmp eq` when reducing signed divisions by power of 2 to
arithmetic shift right, as `icmp ugt` may have been canonicalized
into `icmp eq` by the time additions are folded into `ashr`.

Fixes: https://github.com/llvm/llvm-project/issues/73622.

Proof: https://alive2.llvm.org/ce/z/8-eUdb.
-
Shengchen Kan authored
Split NFC in #73654 into a seperate commit.
-
Michael Buch authored
[clang][DebugInfo] Improve heuristic to determine whether to evaluate a static variable's initializer (#72974)

This patch extracts the logic to evaluate a C++ static data-member's
constant initializer. This logic will be re-used in an upcoming patch.

It also makes the check for whether we are dealing with a constant
initializer more robust/idiomatic, which revealed a bug in the
`debug-info-static-inline-member` test (which existed since its
introduction in https://github.com/llvm/llvm-project/pull/71780)

**Test changes**

* `debug-info-static-member.cpp`:
  * We added the check for `const_b` as part of the
    patch series in `638a8393`.
The check for `isUsableAsConstantExpression` added in the current patch
doesn't support constant inline floats (since they are neither constexpr
nor
    integrals). This isn't a regression since before said patch series
    we wouldn't ever emit the definition for `const_b` anyway. Now
we just don't do it for `inline const float`s. This is consistent with
    GCC's behaviour starting with C++11.

* `debug-info-static-inline-member`:
  * This was just a bug which is now fixed. We shouldn't emit
    a `DW_AT_const_value` for a non-const static.
-
Serge Pavlov authored
Increment and decrement are equivalent to adding or subtracting 1. For
the floating-point values these operations depend on the current
rounding mode. Teach constant evaluator to perform ++ and -- according
to the current floating-point environment.

Pull request: https://github.com/llvm/llvm-project/pull/73770
-
Kohei Yamaguchi authored
Fix broken docs for MeshDialect's pass and Transform dialect's loop
extension.
-
Benjamin Maxwell authored
This reworks the ArmSME dialect to use attributes for tile allocation.
This has a number of advantages and corrects some issues with the
previous approach:

* Tile allocation can now be done ASAP (i.e. immediately after
`-convert-vector-to-arm-sme`)
* SSA form for control flow is now supported (e.g.`scf.for` loops that
yield tiles)
* ArmSME ops can be converted to intrinsics very late (i.e. after
lowering to control flow)
 * Tests are simplified by removing constants and casts
* Avoids correctness issues with representing LLVM `immargs` as MLIR
values
- The tile ID on the SME intrinsics is an `immarg` (so is required to be
a compile-time constant), `immargs` should be mapped to MLIR attributes
(this is already the case for intrinsics in the LLVM dialect)
- Using MLIR values for `immargs` can lead to invalid LLVM IR being
generated (and passes such as -cse making incorrect optimizations)

As part of this patch we bid farewell to the following operations:

```mlir
arm_sme.get_tile_id : i32
arm_sme.cast_tile_to_vector : i32 to vector<[4]x[4]xi32>
arm_sme.cast_vector_to_tile : vector<[4]x[4]xi32> to i32
```

These are now replaced with:
```mlir
// Allocates a new tile with (indeterminate) state:
arm_sme.get_tile : vector<[4]x[4]xi32>
// A placeholder operation for lowering ArmSME ops to intrinsics:
arm_sme.materialize_ssa_tile : vector<[4]x[4]xi32>
```

The new tile allocation works by operations implementing the
`ArmSMETileOpInterface`. This interface says that an operation needs to
be assigned a tile ID, and may conditionally allocate a new SME tile.

Operations allocate a new tile by implementing...
```c++
std::optional<arm_sme::ArmSMETileType> getAllocatedTileType()
```
...and returning what type of tile the op allocates (ZAB, ZAH, etc).

Operations that don't allocate a tile return `std::nullopt` (which is
the default behaviour).

Currently the following ops are defined as allocating:
```mlir
arm_sme.get_tile
arm_sme.zero
arm_sme.tile_load
arm_sme.outerproduct // (if no accumulator is specified)
```

Allocating operations become the roots for the tile allocation pass,
which currently just (naively) assigns all transitive uses of a root
operation the same tile ID. However, this is enough to handle current
use cases.

Once tile IDs have been allocated subsequent rewrites can forward the
tile IDs to any newly created operations.
-
Jonas Paulsson authored
-
Lucas Duarte Prates authored
This introduces assembly support for the Checked Pointer Arithmetic
Extension (FEAT_CPA), annouced as part of the Armv9.5-A architecture
version.

The changes include:
* New subtarget feature for FEAT_CPA
* New scalar instruction for pointer arithmetic
  * ADDPT, SUBPT, MADDPT, and MSUBPT
* New SVE instructions for pointer arithmetic
  * ADDPT (vectors, predicated), ADDPT (vectors, unpredicated)
  * SUBPT (vectors, predicated), SUBPT (vectors, unpredicated)
  * MADPT and MLAPT
* New ID_AA64ISAR3_EL1 system register

Mode details about the extension can be found at:
* https://community.arm.com/arm-community-blogs/b/architectures-and-processors-blog/posts/arm-a-profile-architecture-developments-2023
* https://developer.arm.com/documentation/ddi0602/2023-09/


Co-authored-by: Rodolfo Wottrich <rodolfo.wottrich@arm.com>
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Simon Pilgrim authored
-
Shengchen Kan authored
GenericDomain -> SSEPackedInt

Found by #73654
-
Mariya Podchishchaeva authored
Due to d0d2ee0e clang doesn't perform
qualified name lookup into the current instantiation when it has
dependent bases, because of that `getTypeName` call always returns null
for unknown specialization case. When there is a `typename` keyword,
`DependentNameType` is constructed instead of simply returning null.
This change attempts to do the same in case of `typename` absence.

Fixes https://github.com/llvm/llvm-project/issues/13826
-
Rik Huijzer authored
This patch suggests to change two things. Firstly, it adds a source link above the generated operations docs (above the `emitOpDoc` calls). This link will point directly to the source TableGen file for the group of operations. For example, for the current [`amdgpu`](https://mlir.llvm.org/docs/Dialects/AMDGPU/) page, the link will add a source link below the "Operation definition" heading pointing to [`mlir/include/mlir/Dialect/AMDGPU/IR/AMDGPU.td`](https://github.com/llvm/llvm-project/blob/main/mlir/include/mlir/Dialect/AMDGPU/IR/AMDGPU.td). The link is wrapped in a "op-definitions-source-link" class which could allow for custom styling, but it also looks reasonable without custom styling I think: 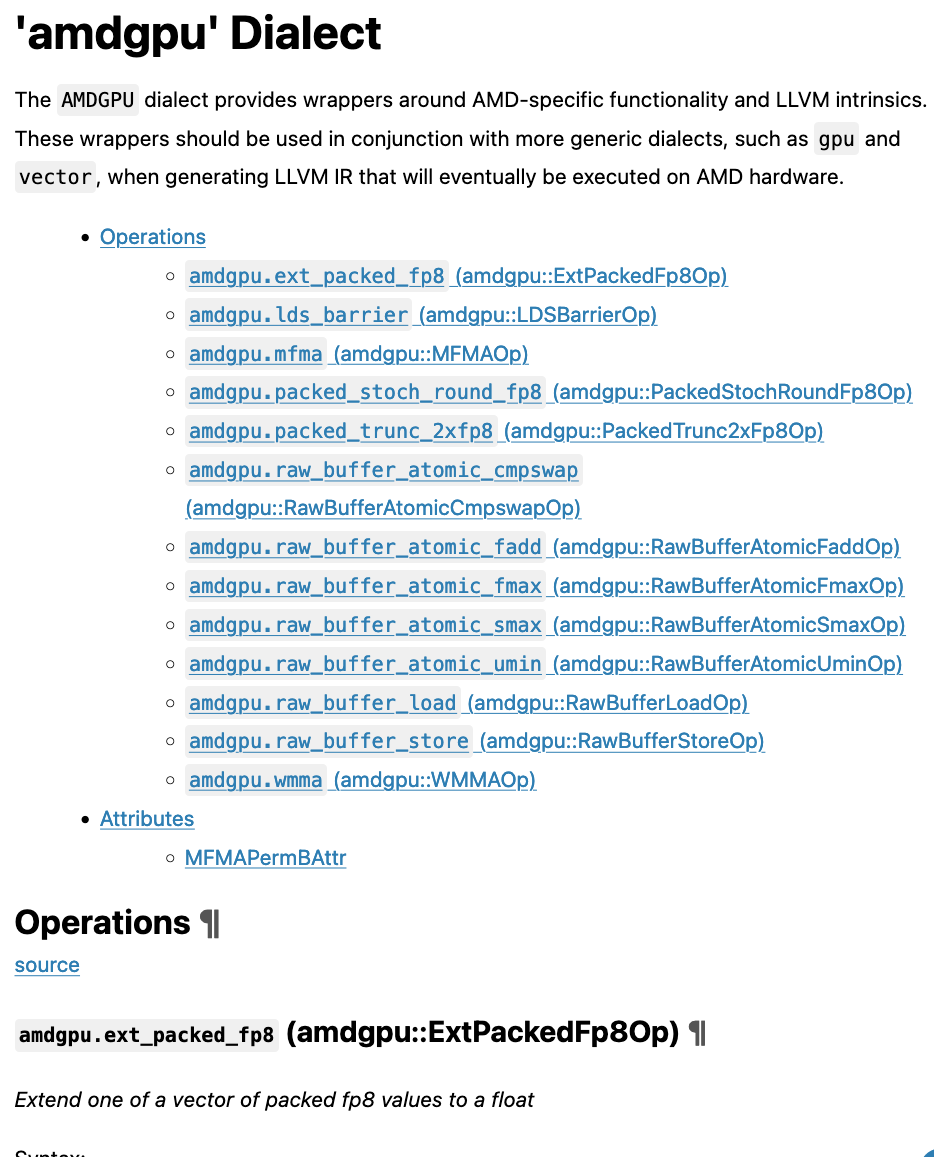 Secondly, this patch simplifies the header names such as "Operation definition" and "Attribute definition" to "Operations" and "Attributes" respec...
-
wanglei authored
Add codegen support for extractelement when enable `lsx` or `lasx`
feature.
-
Nikita Popov authored
When a loop pass that does not preserve MSSA is run as part of a
loop-mssa pipeline, this is user error and we should not ask for
a bug report.

Fixes https://github.com/llvm/llvm-project/issues/73554.
-
Rik Huijzer authored
Out of curiosity, I ran [typos](https://github.com/crate-ci/typos)
against MLIR. It found two `CHECK:` typos (and many minor typos; which
I'm not gonna work on today).
-
Shengchen Kan authored
-
Rik Huijzer authored
Currently, the only mention of 0d vectors in the MLIR source code that I
could find was:

>     0D vectors are allowed by omitting the dimension: `vector<f32>`.

in
[`BuiltinTypes.td`](https://github.com/llvm/llvm-project/blob/437a48b2d9bfc6e38a0ca43f1cee48ceaf0fe249/mlir/include/mlir/IR/BuiltinTypes.td#L1046-L1047).

This patch adds a summary of
https://discourse.llvm.org/t/what-is-the-semantics-of-memref-0xf32-and-tensor-0xf32/3557
and https://discourse.llvm.org/t/should-we-have-0-d-vectors/3097/5.
-
Shengchen Kan authored
KMOV is essential for copy between k-registers and GPRs. R16-R31 was added into GPRs in #70958, so we extend KMOV for these new registers first. This patch 1. Promotes KMOV instructions from VEX space to EVEX space 2. Emits prefix {evex} for the EVEX variants 3. Prefers EVEX variant than VEX variant in ISEL and optimizations for better RA EVEX variants will be compressed to VEX variants by existing EVEX2VEX pass if no EGPR is used. RFC: https://discourse.llvm.org/t/rfc-design-for-apx-feature-egpr-and-ndd-support/73031/4 TAG: llvm-test-suite && CPU2017 can be built with feature egpr successfully. -
Jie Fu authored
/llvm-project/clang/lib/Sema/MultiplexExternalSemaSource.cpp:317:2:
error: extra ';' outside of a function is incompatible with C++98 [-Werror,-Wc++98-compat-extra-semi]
};
 ^
1 error generated.
-


